
How routing is changing
Previously, Providers Inference selected one provider and returned its error if a request failed. OpenRouter now evaluates providers using current metrics and chooses the best balance of price, speed and reliability. If a provider slows down or starts failing, traffic is redirected, and the failed request is retried with the next suitable provider within the same call.
According to OpenRouter’s measurements, the new routing reduced errors related to insufficient capacity by 46%. Time to first token improved by 16.9%, and throughput by 16.3%.
For each model, you can keep the default policy or specify a preference in the model ID:
zai-org/GLM-5.3            # default: best mix of price, speed and reliability
zai-org/GLM-5.3:fastest    # highest throughput
zai-org/GLM-5.3:cheapest   # lowest price
zai-org/GLM-5.3:novita     # only Novita
By default, the system selects the best balance of price, speed and reliability. The :fastest, :cheapest and :novita suffixes specify the highest throughput, lowest price or Novita as the sole provider, respectively.
Source: huggingface.co
Routing also takes prompt caching into account: a conversation stays with the provider that holds its cache. To pin a session explicitly, you can pass a persistent conversation UUID in the X-HF-Session-Id header. See the prompt caching guide for details.
Source: huggingface.co
Growth in open models and the price gap
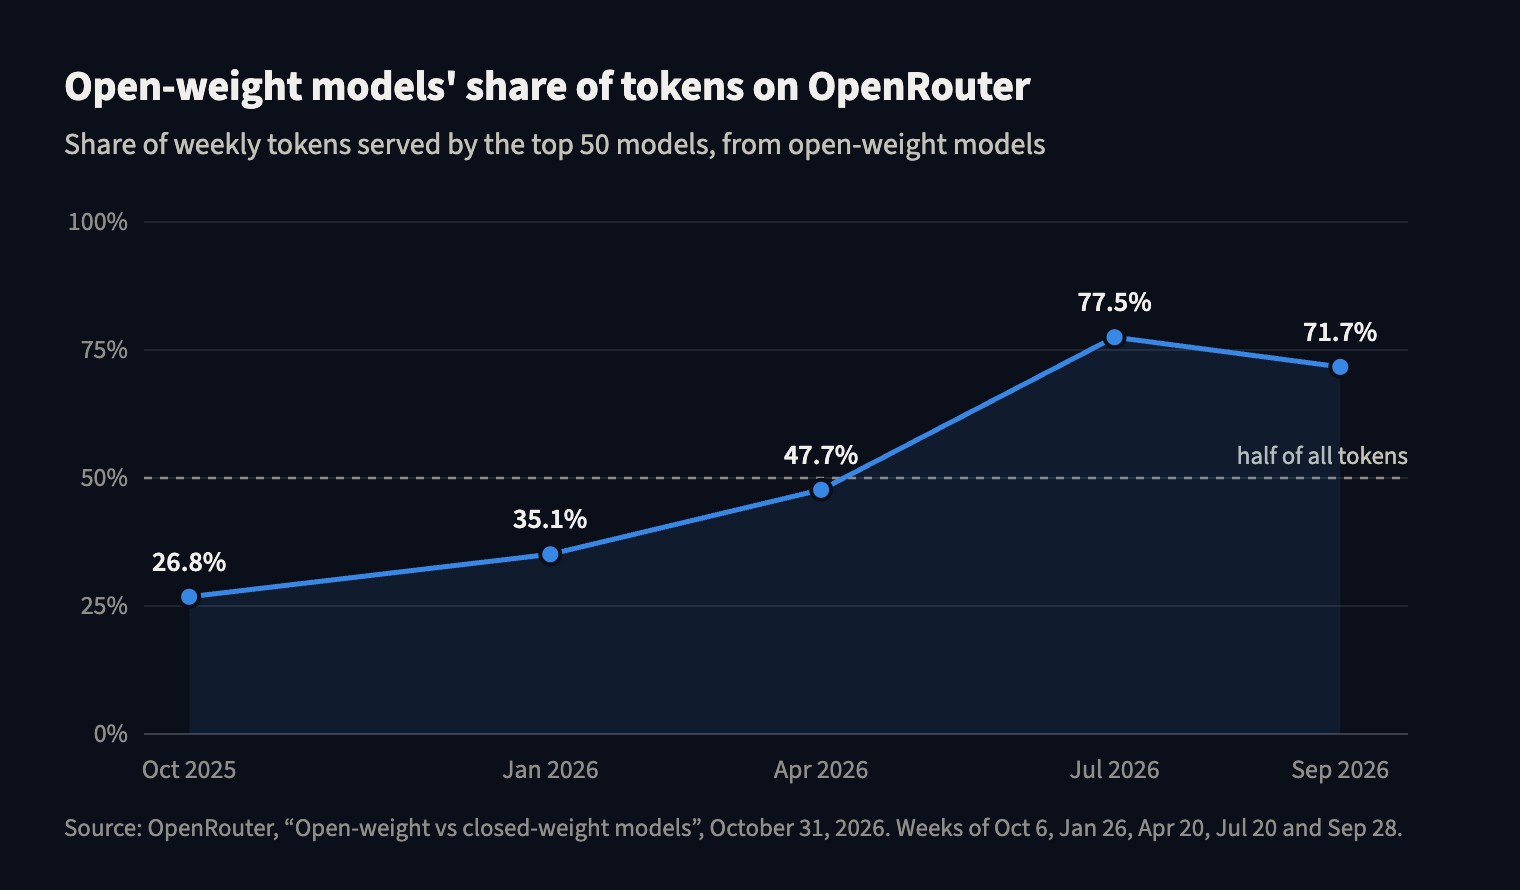
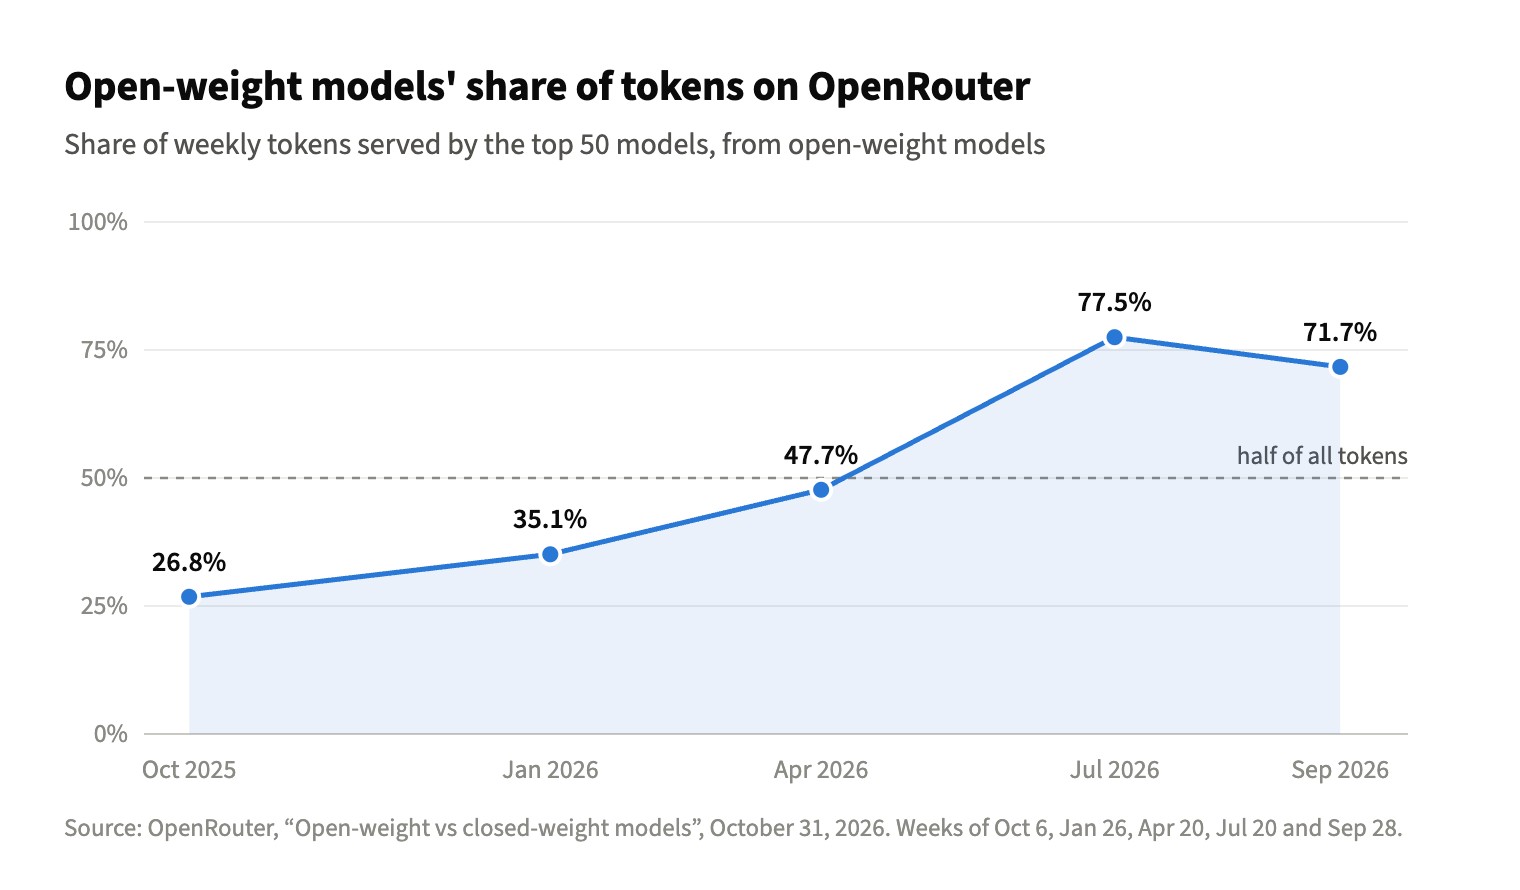
On OpenRouter, the share of tokens processed by open-weight models rose from 26.8% in October 2025 to 71.7% at the end of September 2026. It reached 77.5% in July. Over the same period, weekly volume for these models increased more than 60-fold, while volume for closed models grew nearly 10-fold. According to the rankings, this week’s most-used OpenRouter model is the open-weight DeepSeek V4.1 Flash 1017, with 59.2 trillion tokens. Data source: OpenRouter, October 2026.
Open-weight models cost about four times less on average. One million input tokens cost $0.28, and one million output tokens cost $1.62. For closed models, the corresponding prices are $1.27 and $6.36.
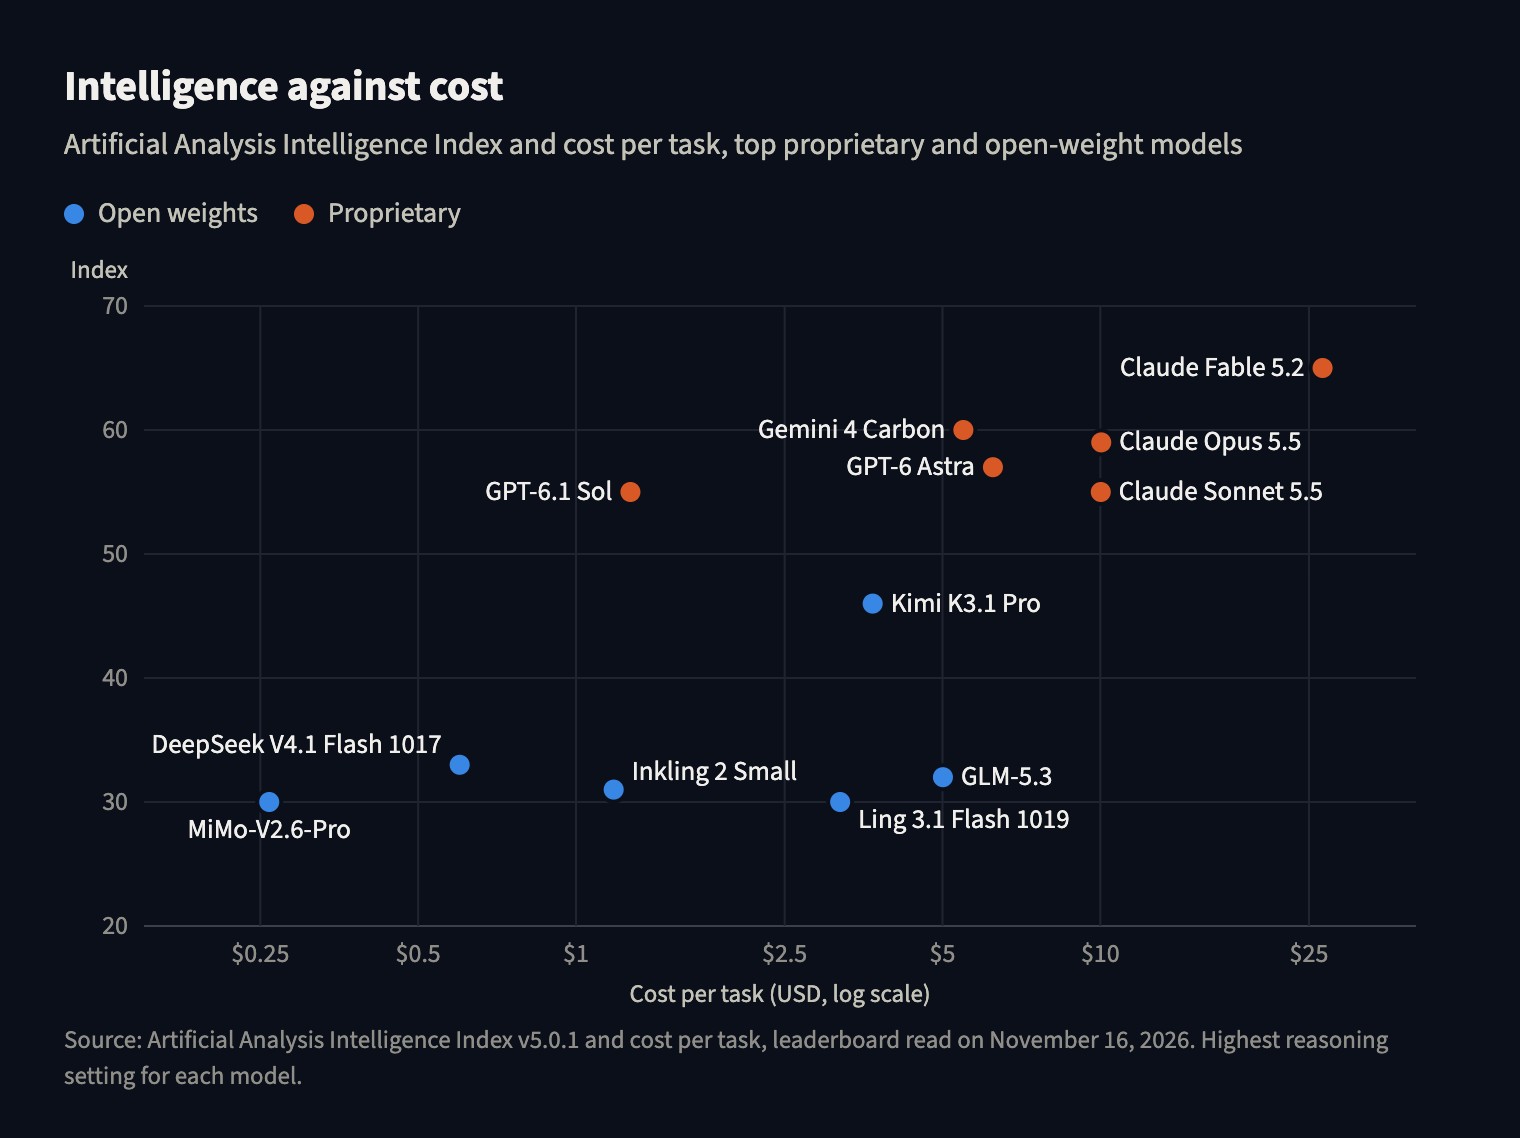
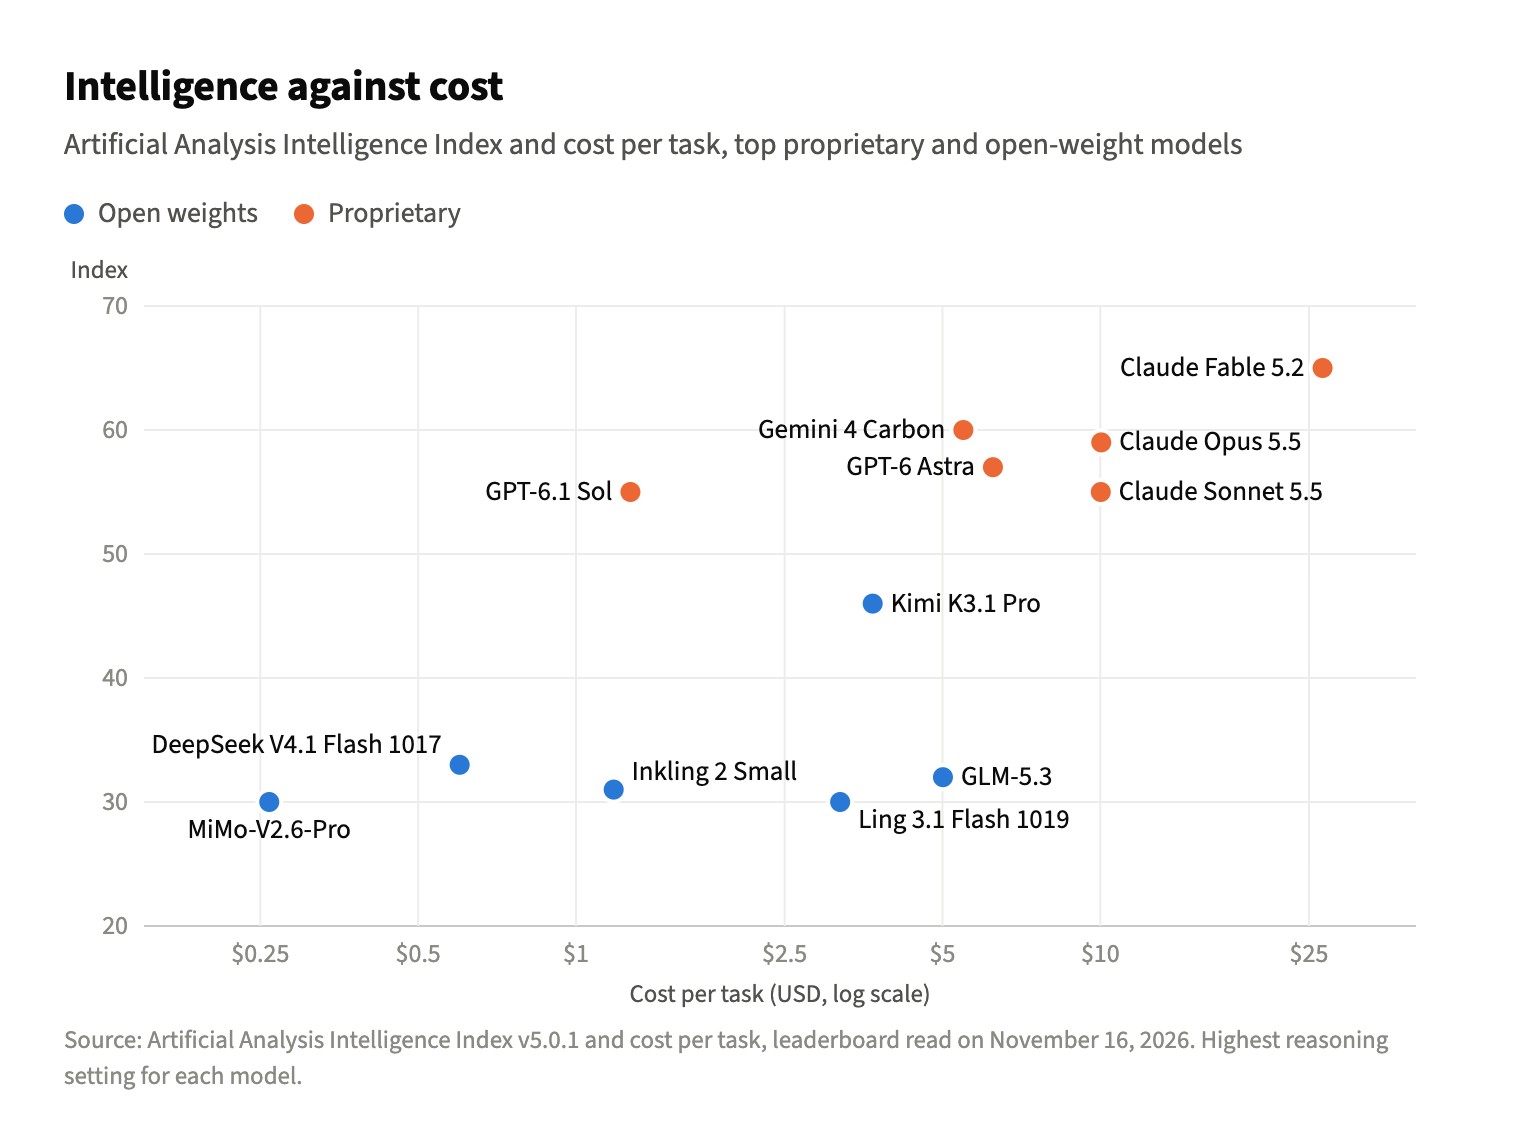
On the hardest benchmarks, the best open-weight models still trail the best proprietary models. On the Artificial Analysis Intelligence Index, Kimi K3.1 Pro scored 46, compared with 65 for Claude Fable 5.2. But a task with Kimi costs about one-seventh as much as with Claude: $3.68 versus $26.54. For many types of work, that trade-off makes sense.
Source: huggingface.co
Compatibility and settings
For all conversational models, the router supports OpenAI’s Chat Completions and Responses APIs, as well as Anthropic’s Messages API, regardless of which provider handles the request. Users can choose a coding agent or a software stack and model, then follow setup instructions or hand the entire setup over to their agent.
Source: huggingface.co
Source: huggingface.co
Access to other Hugging Face services remains available with the same token: Storage Buckets, compute through Jobs, and dedicated inference through Inference Endpoints. PRO, Team and Enterprise plans include monthly credits for compute and inference.
Source: huggingface.co
Source: huggingface.co
Source: huggingface.co
Model prices are unchanged: users pay the provider’s rate through their Hugging Face bill, with no additional markup from Hugging Face. PRO users receive $2 in monthly credit, while Team and Enterprise organizations receive $2 per seat. See the Pricing and Billing sections for details.
Image, video and audio generation will continue to work as before, directly through Hugging Face Providers Inference, without OpenRouter. The same token and API remain available, as does access to tens of thousands of LoRAs.
Where to find request details
Model pages let you chat with a model directly through a widget. The Providers tab shows every provider OpenRouter can route a request to, along with its input and output token prices, speed and availability over the past 24 hours. The Metrics tab brings together the best provider figures for price, throughput, time to first token, context length and availability.
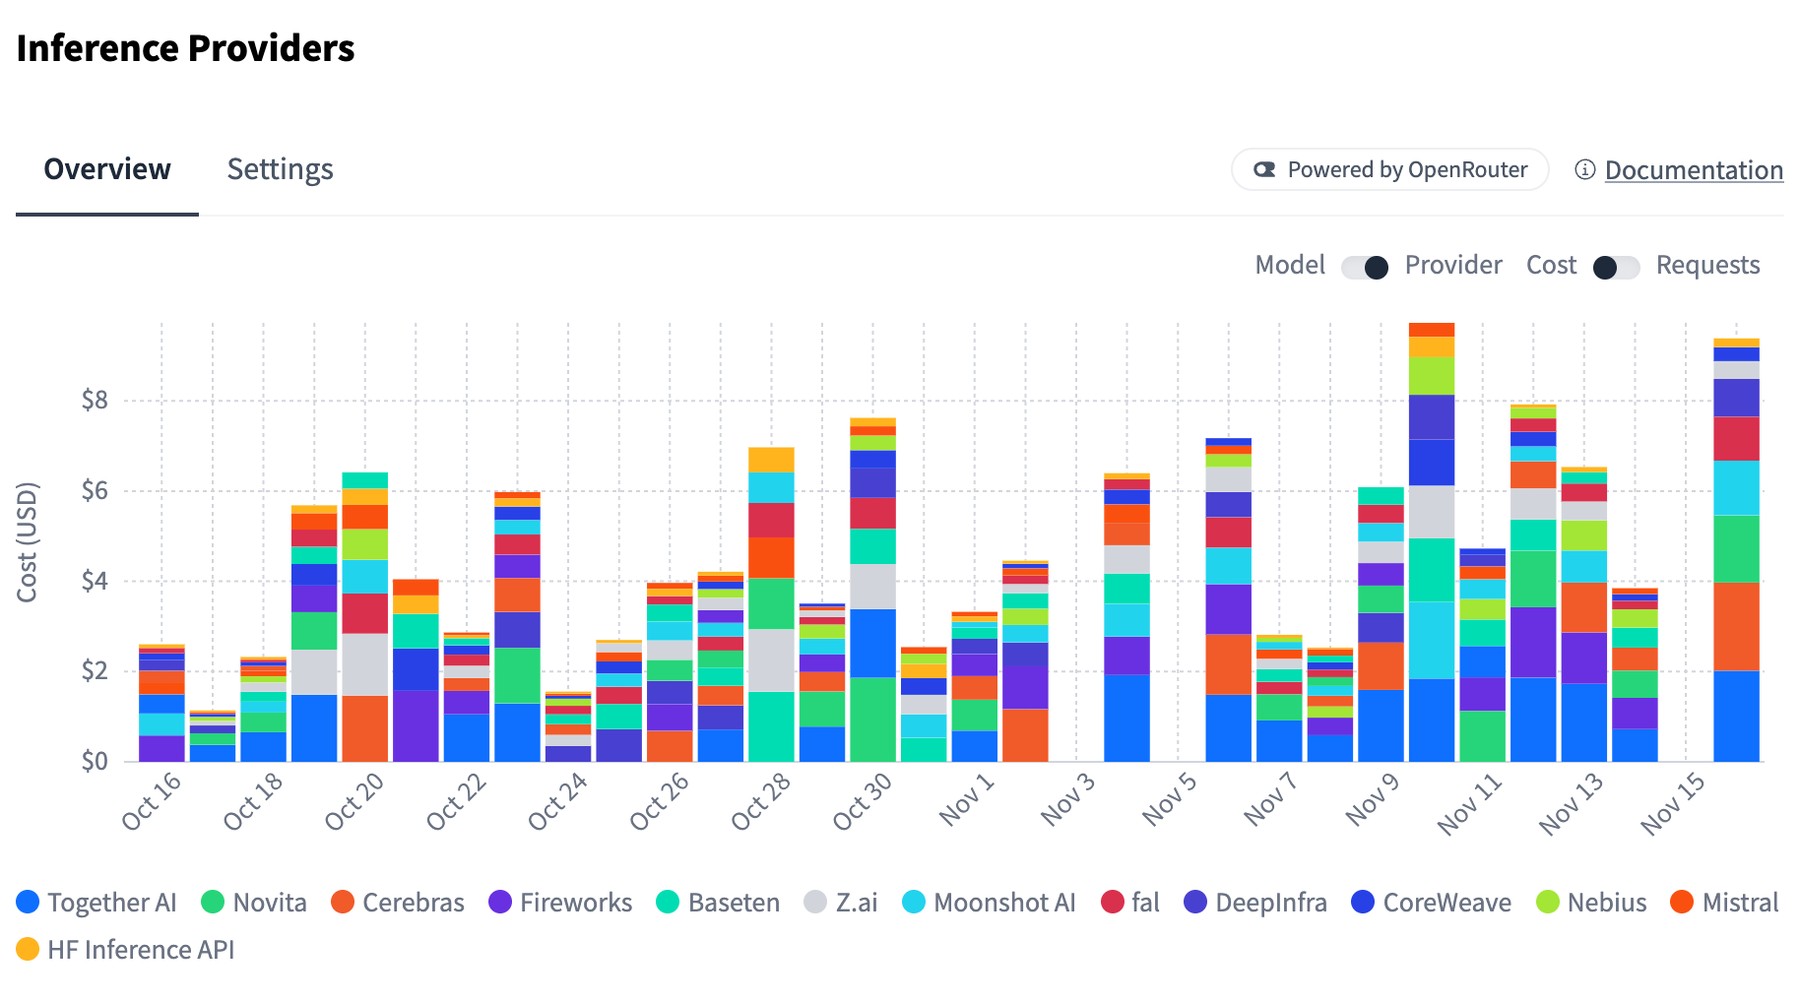
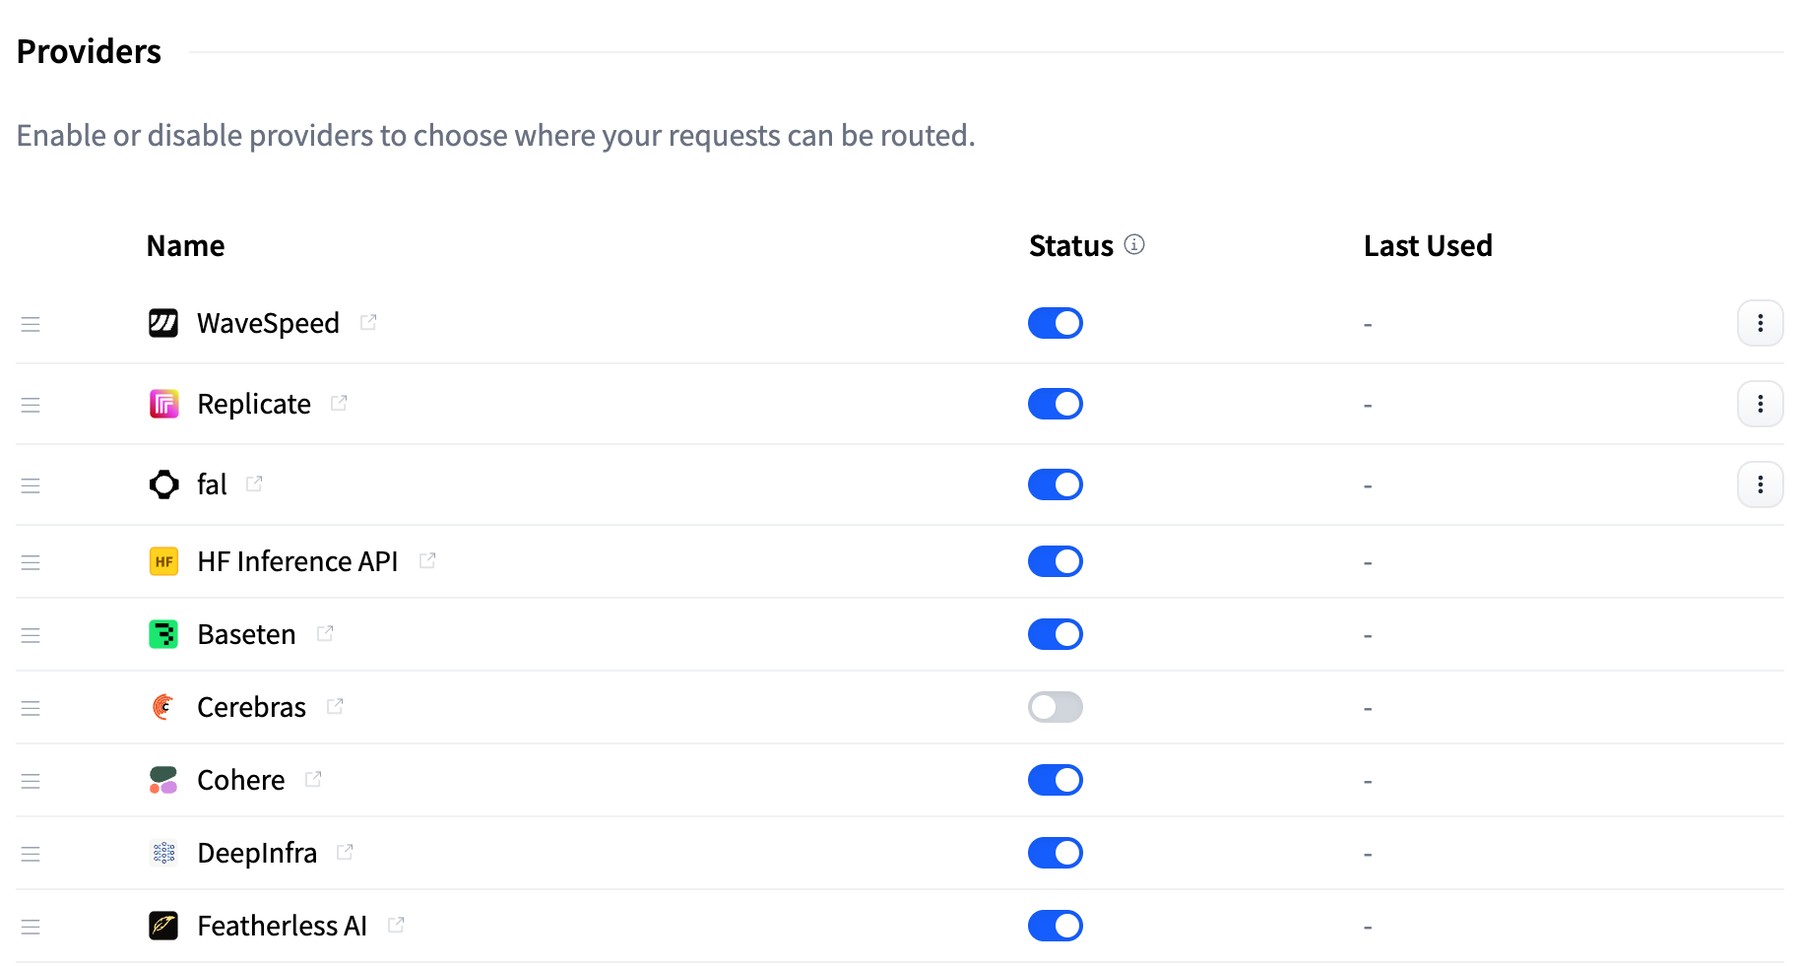
The usage overview breaks down spending by provider. In settings, you can disable any provider, and the router will stop sending it requests. Organizations have the same settings, which apply to all requests paid for by the organization.
Limitation on using your own keys
Language model requests now go through OpenRouter and are charged to the user’s or organization’s Hugging Face account. As a result, you can no longer connect your own provider API key to these models. Instead, you can select a provider with a suffix in the model ID — model:provider — or disable it in settings; no code changes are required. Your own keys for image and video providers will continue to work.
What comes next
The move to OpenRouter is the first stage of the partnership. Hugging Face plans to add the option to connect an OpenRouter account and route more types of tasks through it. To get started, choose a model or consult the Providers Inference documentation.
Dataist’s take: The new setup makes it easier to choose a provider and improves request resilience, but changes how users pay and removes the option to connect their own provider keys for language models. Image, video and audio generation will remain outside OpenRouter routing.
Daily AI news
Every day we pick what actually matters in AI and explain it plainly — no hype, no filler. Subscribe if you want to follow where the industry is going.
Only what matters — every day
Follow on X