
Source: venturebeat.com
What changed
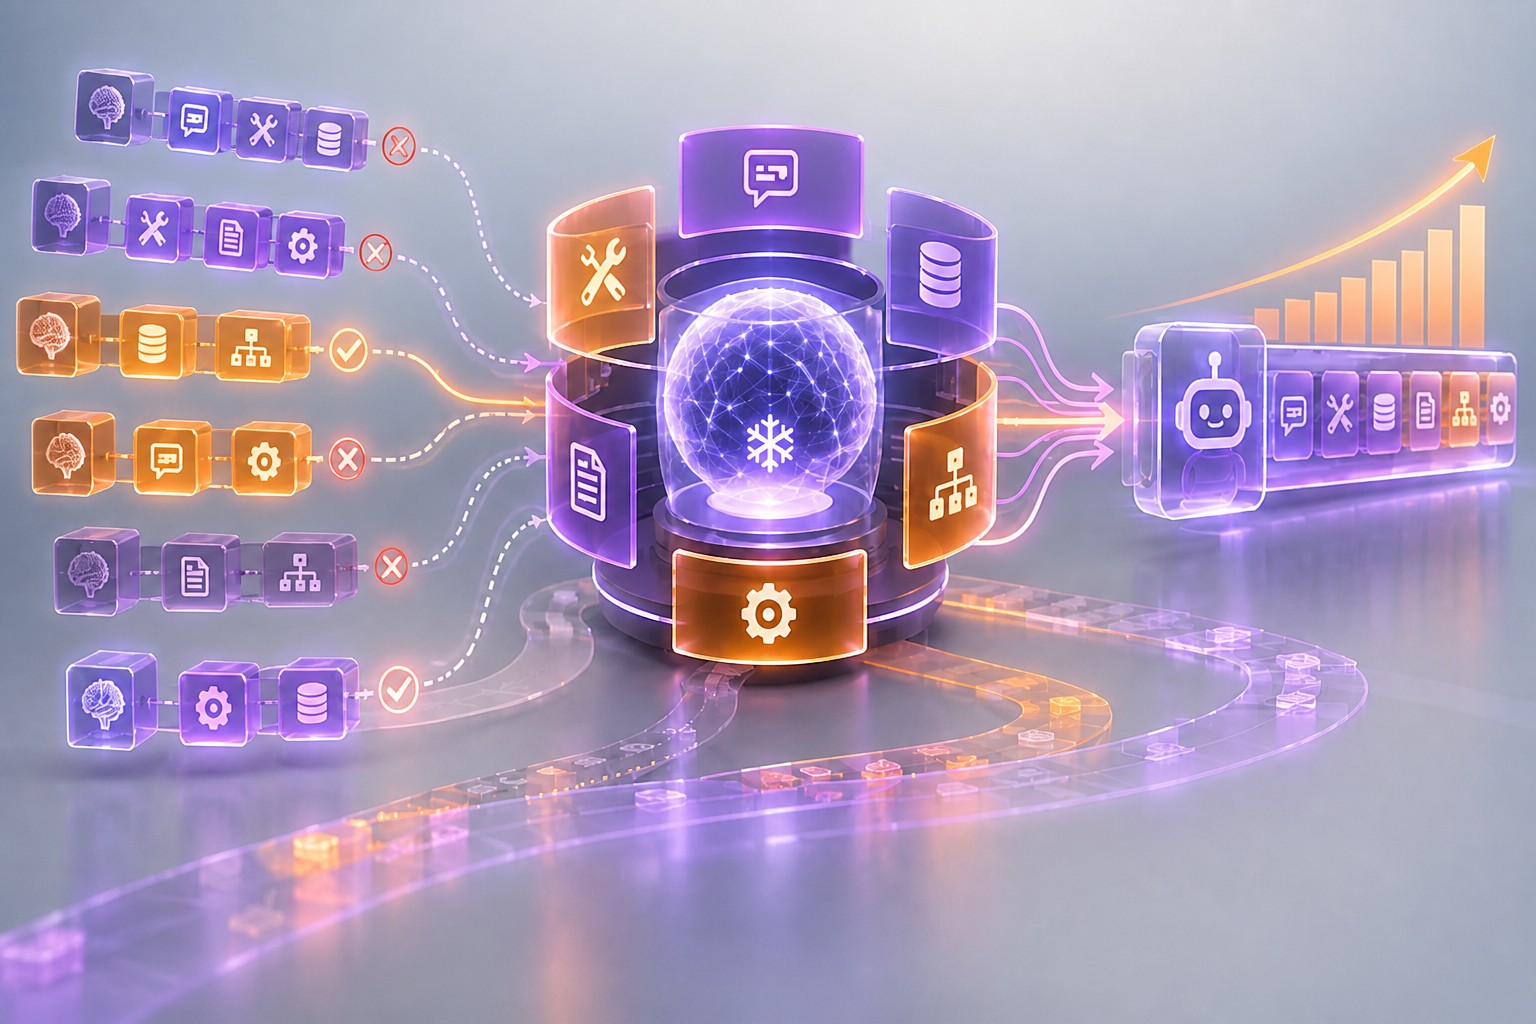
Salesforce AI Research and Salesforce Agentforce built DarwinX around a population of agent-framework variants rather than one version that is repeatedly edited.
The system:
The base LLM remains unchanged. DarwinX modifies the agent framework: prompts, tools, skills, memory, control logic and source code.
The browser result came from WebArena-Infinity. DarwinX evolved a browser framework on 300 synthetic intents generated from application documentation, then tested it on 1,260 previously unseen tasks with deterministic evaluators. The result was measured with GPT-5.5 and followed a filtering process that removed trajectories showing unacceptable or exploit-like behavior.
Salesforce also tested the approach on other benchmarks:
The Terminal-Bench gains were not simply the result of making the agent think longer. On tasks both versions could solve, the median number of steps rose from 12 to 13. On six tasks solved only after the changes, it rose from 11 to 22. The framework appears to have learned when additional checks and retries were worth the cost.
The seven new skills added to the agent included instructions to:
Why one improving version is not enough
Most agent self-improvement systems follow a familiar loop:
The problem is that every change can alter the future search space. A fix that helps one task may damage another, and a locally successful version can become the foundation for every later change.
Salesforce researchers compare DarwinX with two earlier approaches. Darwin Gödel Machine, or DGM, lets an agent modify its own source code and keeps an archive of previous versions, but changes one parent at a time. HarnessX works with prompts, tools and control logic, and separates variants by task families to limit interference. DarwinX adds explicit preservation checks and the ability to combine different branches.
The path-dependence problem is easy to see in software work. An early change might teach a coding agent to install dependencies aggressively before starting. If that fixes several failures, it becomes the new baseline. Later improvements are built on top of it, while an alternative strategy—first inspecting the environment and installing only what is needed—may never get the chance to develop.
The second problem is interference between tasks. An instruction to perform an extensive check could improve difficult scientific-computing tasks while causing simpler tasks to exceed their time limits. The broader the agent’s task portfolio, the harder it becomes to improve one capability without sacrificing another.
Evaluation itself is noisy. The same agent can pass a task in one run and fail it in another, and previous work cited by the researchers found fluctuations of several percentage points between runs of industry benchmarks. That can be as large as the visible effect of an individual framework change.
DarwinX therefore treats regression testing as part of the search, not as a final release step. A candidate must show that it added something useful while preserving earlier capabilities within defined limits. A small negative effect may be tolerated during early exploration, but the candidate must pass a more accurate confirmation stage before it can guide future evolution.
For programming and browser tasks, this is practical because the outcome can usually be checked. In WebArena-Infinity, Salesforce used an LLM-based judge while evolving variants, then used deterministic checking procedures for the final evaluation.
The value of keeping weaker branches
DarwinX does not discard every variant with a lower overall score. A branch that performs worse on average may contain the only behavior that solves a particular class of tasks.
That matters because aggregate scores can conceal useful specialization. In the TerminalWorld experiment, four specialized variants solved 24, 25, 26 and 27 held-out tasks on different overlapping sets. The merged framework solved 28 and exceeded every individual variant.
The result was not universal. The researchers call the Opus 4.8 result the main one because the same procedure on GPT-5.5 produced 56.1%, below the neutral baseline agent. They describe the one-task advantage over the best standalone agent as informative but not statistically conclusive.
For a company, the analogy might be an incident-response agent. One general version could reliably inspect services, run standard diagnostics and prepare safe code changes. A weaker branch might specialize in checking Kubernetes permissions, while another focuses on database recovery and artifact verification. Neither needs to be good enough to deploy independently. Its framework changes may still be useful when combined with other branches and tested again for regressions.
That is the more interesting claim behind DarwinX: not that evolution discovers one superior agent, but that a useful behavior should not be lost merely because its original branch has a mediocre average score.
The framework can propose changes from:
It can also group repeated failures into shared memory. If several tasks fail because environment setup takes too long, the system may propose a reusable setup skill instead of separate fixes for every task.
The process is not evaluation-free. DarwinX still needs a signal that tells it whether a task was completed. The difference is that researchers do not have to inspect every candidate and pick a winner manually; variants survive according to measured fitness from task evaluators.
The part Salesforce cannot automate away
DarwinX is most relevant to application developers because it operates at a layer they already control. They do not need access to model weights, their own fine-tuning pipeline or a new base model.
That layer also contains information a general-purpose model cannot simply acquire during pretraining:
As models improve their general reasoning, the surrounding framework may carry more of the company-specific context and operational behavior. In my view, that makes the framework a more durable source of product differentiation than any individual prompt.
But the hard part is not producing candidate changes. It is defining “better” for production work.
Programming benchmarks often have a clear checker. Enterprise workflows usually do not. Salesforce’s proposed answer is to turn real operational traces into evaluation signals. For a support agent, those signals could include:
Some can become deterministic tests: whether a ticket reached the correct state, an approved operation completed, or an expected database value appeared. Others may come from employee corrections, compliance reviews, business results or agreement between several evaluators.
This is the question the announcement is relatively quiet about: who defines the regression suite when the agent’s work is not naturally binary? The evolution machinery can search efficiently, but it cannot decide whether a customer interaction, approval process or operational exception was handled correctly unless the company has already encoded that judgment somewhere.
Rang Xu, the senior author of the DarwinX paper, told VentureBeat that manually developing an agent framework can easily converge on a local optimum: a team fixes a prompt or workflow for one kind of failure, but without broad regression testing may quietly break something that worked before.
Xu’s proposed solution is not necessarily one perfect reward function. Companies need infrastructure that continuously turns real work into better corporate information. Over time, that could create a maintained test set based on the workflows agents actually encounter, allowing teams to evolve agents on representative substitute tasks rather than live requests.
Salesforce has released Beagle, an open framework on GitHub under the Apache 2.0 license, to support these experiments. Monet remains closed, but teams can connect their own agent framework to Beagle. DarwinX supplies the evolution method; Beagle provides broader infrastructure for running experiments with agents, environments, datasets and evolution methods.
Xu describes Beagle as a “Hugging Face Trainer for AI agent evolution”: developers bring the agent, environment, evaluation signal and evolution algorithm, while the infrastructure handles large-scale runs and experiments.
That infrastructure is not free. DarwinX explores several variants, repeats evaluations to account for noisy results and runs preservation checks before candidates can influence later generations. The cost includes inference, engineering time and the risk of regressions. A fixed compute budget can limit the search, and evolution can stop when another improvement no longer justifies its price.
I think that makes DarwinX a targeted tool, not a default architecture for every agent. It fits long-running tasks with a broad behavior surface and an outcome that can be evaluated with reasonable confidence:
For a stable process that turns a known input into a fixed API call, a deterministic workflow is easier to understand, test and control. The practical middle ground may be simpler: turn recurring failures and employee feedback into proposed changes, then run those changes against a regression set without maintaining a full population of variants.
The result from Salesforce is therefore less a claim that models no longer matter than a demonstration that their surrounding software remains underdeveloped. DarwinX found substantial headroom without touching model weights—but that headroom is useful only when a company can measure what must be preserved. The next competitive layer for agents may be the testing system that decides which improvements are safe to keep.
Daily AI news
Every day we pick what actually matters in AI and explain it plainly — no hype, no filler. Subscribe if you want to follow where the industry is going.
Only what matters — every day
Follow on X