
What xAI shipped
xAI says Grok 4.7 is built on a larger base model, trained for longer with reinforcement learning, and better at checking its own results. The model is available through:
The pricing is the clearest positioning signal. At $2 per million input tokens and $6 per million output tokens, Grok 4.7 sits closer to Chinese models than to the leading Western models. The source does not establish that the price was set because of the benchmark results, but the combination is hard to ignore.
The benchmark gap
Artificial Analysis Intelligence Index v4.3.2, an independent index combining ten benchmarks, gave Grok 4.7 a score of 46. Claude Fable 5.1 and GPT-6 led the ranking with 53 points each, leaving Grok 4.7 in the middle.
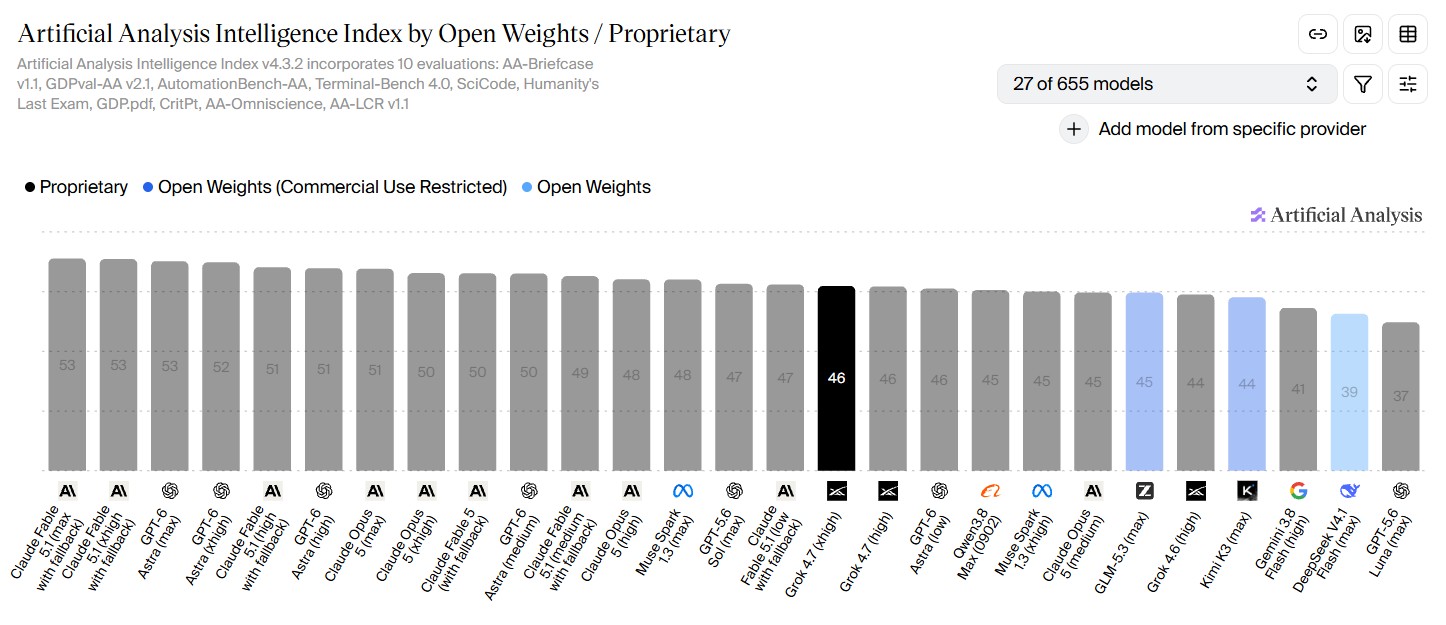
Grok 4.7 (black) scores 46 overall, well behind Claude Fable 5.1 and GPT-6 at 53 each. Its two highest reasoning levels appear to perform about the same. | Image: Artificial Analysis
Source: the-decoder.com
The gap becomes larger when the task involves AI agents writing code. In Terminal-Bench 4.0:
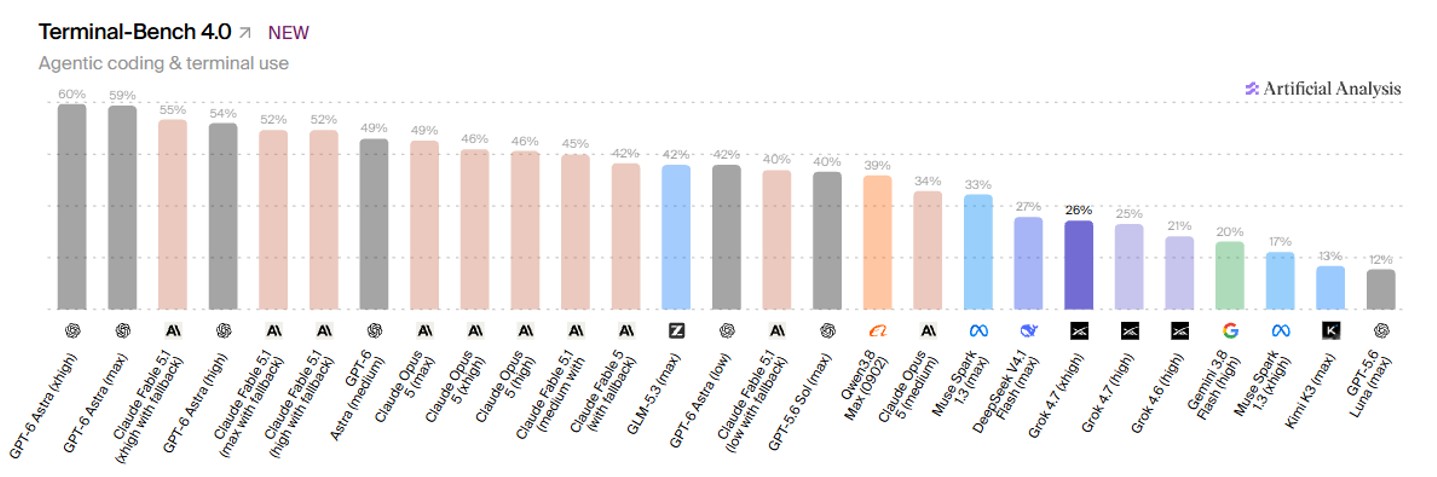
Grok 4.7 scores 26 percent on Terminal-Bench 4.0's agentic coding test, far behind GPT-6 Astra (60 percent) and Claude Fable 5.1 (55 percent). | Image: Artificial Analysis
Source: the-decoder.com
That last comparison matters. Grok 4.7 is not only behind the two leading models; it was also beaten by the cheaper DeepSeek V4.1 Flash, which scored 27%.
A cheap model with an expensive question
My read is that xAI is selling Grok 4.7 on access economics rather than benchmark leadership. Lower token prices can matter to developers running large workloads, but the agentic coding result cuts directly against the model's stated role. A system intended for programming has less room for weakness when it must plan, execute and verify work across a terminal.
The announcement is quiet about the trade-off xAI expects customers to make. It explains the training changes and lists the platforms, but it does not show how much performance users give up for the lower price. For simple or high-volume workloads, that may be acceptable. For autonomous coding, the numbers suggest that price alone does not close the gap.
The practical tension is now clear: Grok 4.7 is easier to afford, but the tasks most likely to justify using an advanced model are where its disadvantage is largest.
Daily AI news
Every day we pick what actually matters in AI and explain it plainly — no hype, no filler. Subscribe if you want to follow where the industry is going.
Only what matters — every day
Follow on X