Universal Deep Research compiles a written strategy into runnable code
When people say “deep research,” they usually mean a service that plans its own search, walks through sources, collects citations and hands back a tidy report. Convenient — and almost always locked to a single strategy and a single model family. The authors of Universal Deep Research (UDR) propose a different arrangement: let the user pick any LLM and write the research strategy themselves, with no model training and no elaborate setup. In practice it is a wrapper around an LLM plus a compiler that turns a natural-language strategy into executable code you can inspect, repeat and edit.
Why separating the model from the strategy matters
Today's deep research tools — Gemini, Perplexity, OpenAI Deep Research, Grok DeepSearch — search well and format a clean report, but they hide the important levers. The user has almost no say over source priorities, cross-validation or the cost of calls, cannot swap in their own preferred LLM as the system's brains, and above all cannot describe their own domain-specific tactics. That hits hardest in finance, law, healthcare and other high-value domains, where mistakes are expensive and the bar for verifying sources is high.
UDR tries to close three gaps at once:
- flexible control over sources, checks and budget;
- the ability to write specialized strategies for a domain;
- free composition: any strategy can run on any LLM.
How it works inside
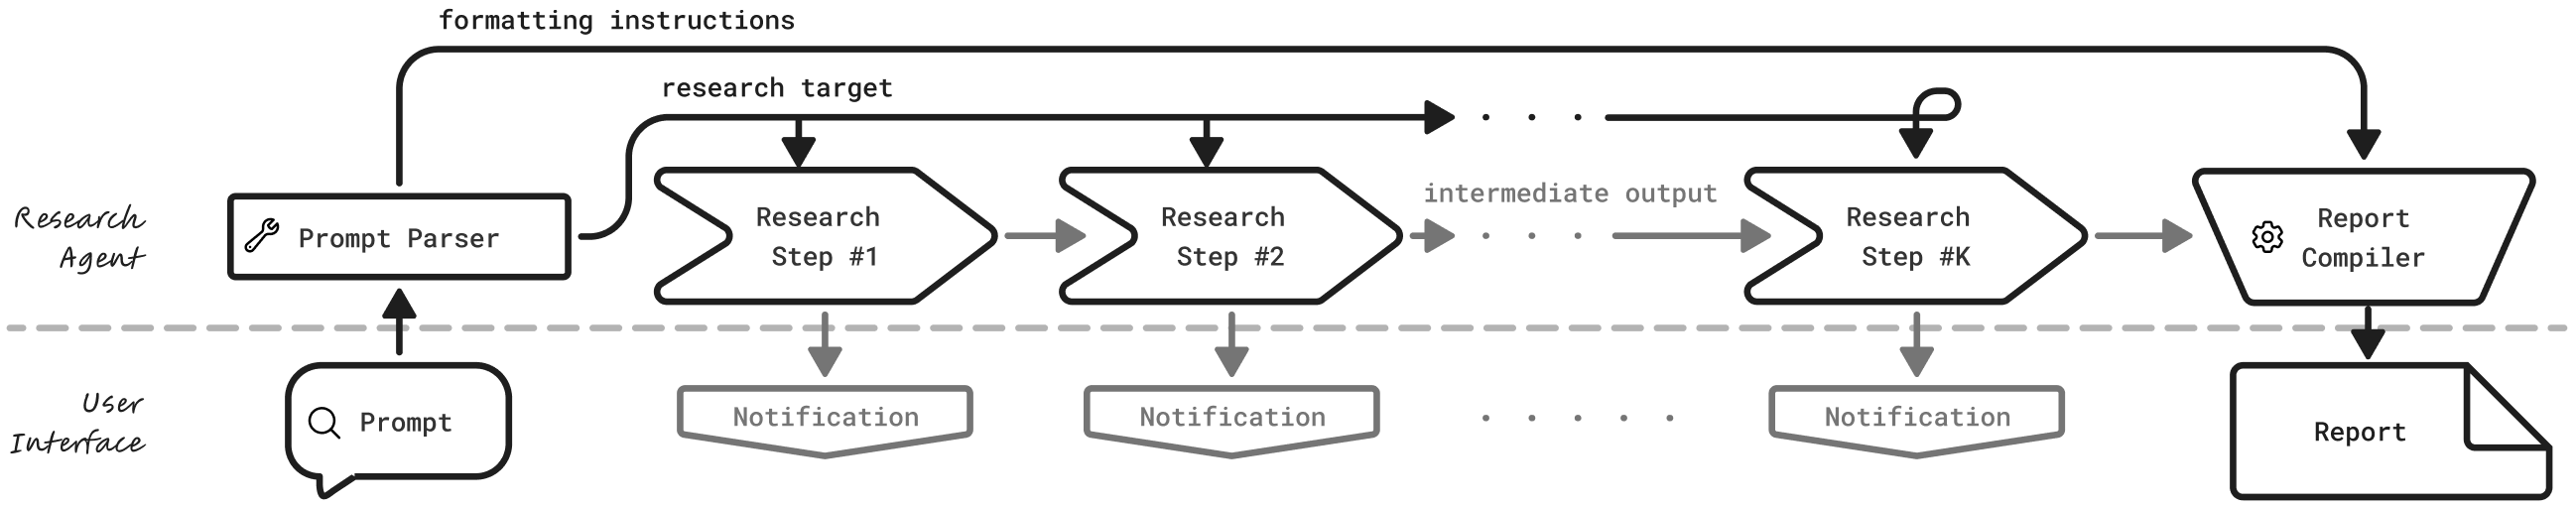
The system runs in two phases. First, a strategy written as a plain list of steps in human language is turned by an LLM into a single executable program with explicit control flow and a limited tool set (search, ranking, extraction and so on). At this stage the model is held to strict correspondence: every piece of code carries a comment naming the step of the strategy it implements. That sharply reduces the risk of the LLM cutting corners, skipping a step or adding constraints of its own.
The code then runs in an isolated sandbox with deterministic tool calls. All intermediate data lives in named state variables rather than in a growing chat context, so even a small context window is enough — 8k in the experiments. The LLM's reasoning is used as a utility: summarization, fact extraction, ranking. Orchestration is ordinary code on the CPU, not hidden magic inside a prompt. The user follows progress through a stream of notifications, and the strategy itself decides when and what to show.

What the approach buys you
- Reliability. A single program turned out to be more stable than long reasoning prompts or step-by-step generation of fragments. Fewer cascading failures, easier to audit.
- Efficiency. Splitting the roles lowers cost: the LLM is called only where its intelligence is actually needed, not for the whole process.
- Transparency. Notifications, state variables and a reproducible final report make the path to the result traceable.
- Safety. Running in isolation limits the risk from user-supplied code — an important point for enterprises.
The authors show three families of strategies: minimal (a quick pass), expansive (broad topic coverage) and intensive (several iterations that rethink the search phrases). Each can be edited to fit the job, from testing hypotheses in R&D to legal document review. Crucially, UDR does not impose agency of its own: if the strategy does not call for free-form reasoning, the system will not improvise.
An interface for experiments
On top of the core sits a simple UI: enter the prompt, pick and edit the strategy, watch the notification stream, read the report. You can stop a run and generate an interim result.

In the demos, the minimal strategy running on Llama 3.3 70B confidently produced tidy reports on cultural and historical queries, on dates and news days, and on biographies with requirements for structure and links. One detail matters here: following the rule “only from what was read into context” disciplines the model and lowers the risk of invention.

Why this matters
UDR draws a clean line between models and agent logic. That opens the door to new, vetted strategies for mass-market scenarios. LLM vendors can compete on the quality of reasoning and developers on the quality of strategies, without getting in each other's way. For organizations it is a route to controlled, reproducible research with clear management of cost and risk.
AI paper breakdowns
Every day we read the new AI papers and retell what matters in plain language — no hype, no filler. If you want to see where AI agents are heading before everyone else, subscribe.
New breakdowns every day.
On Telegram