
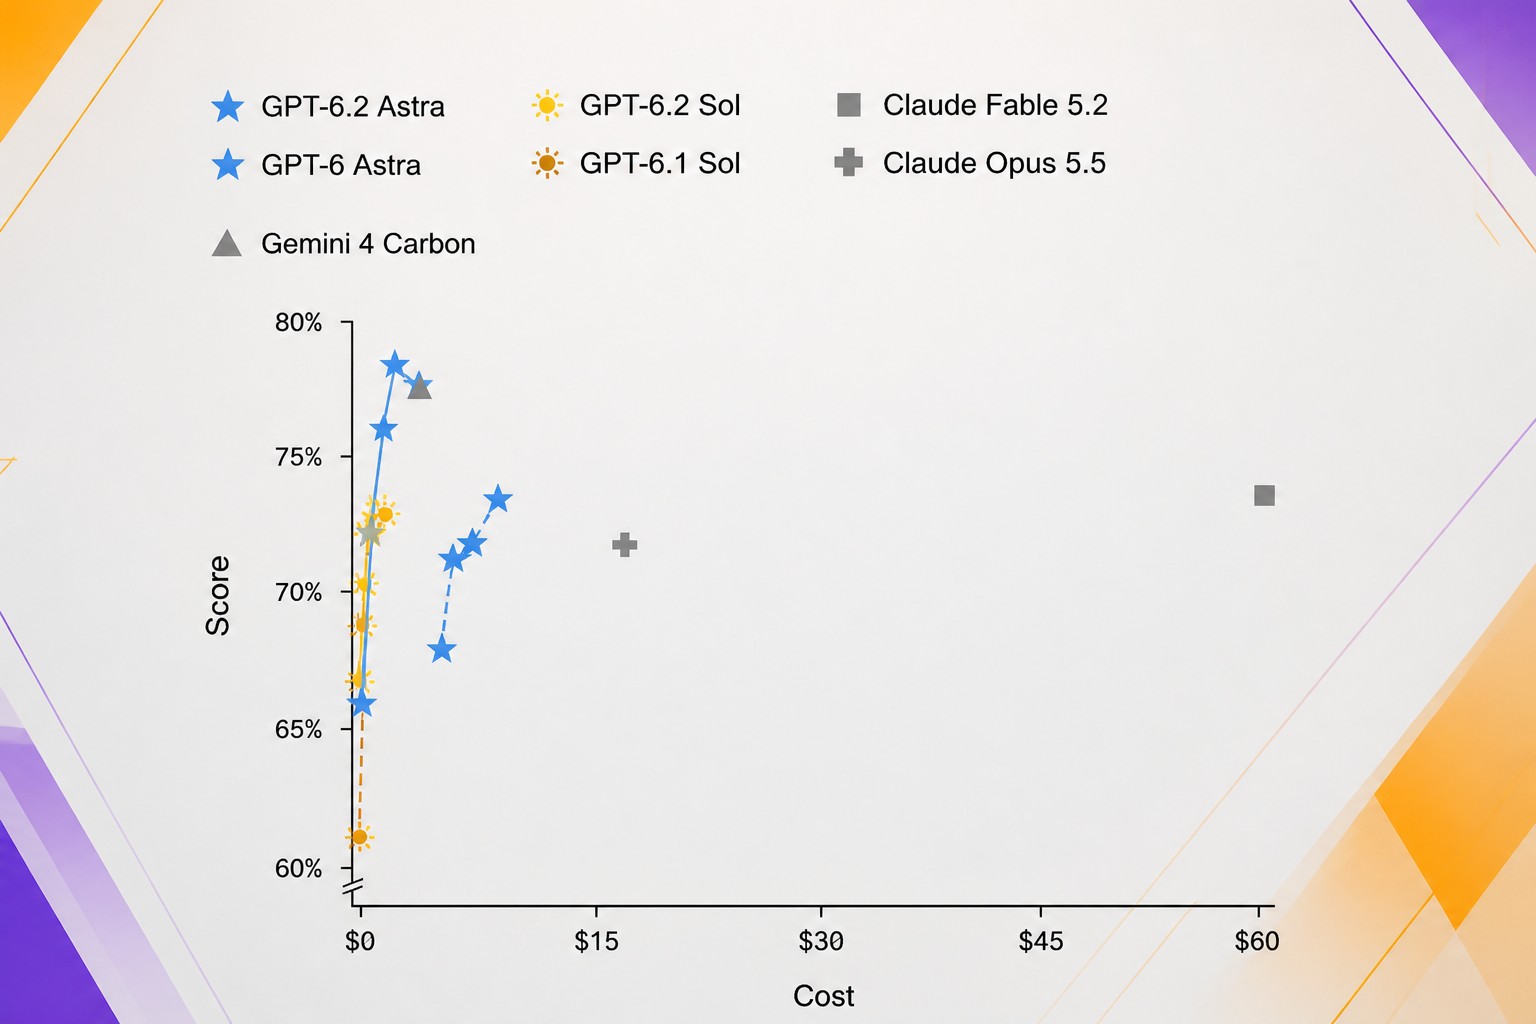
Access and pricing
Pro-500 users can enable Ultrafast mode for both models. Pro-200 subscribers have also gained access for the first time, for now only with GPT-6.2 Sol.
GPT-6.2 Astra costs $8 per million input tokens, $0.40 per million cached input tokens and $40 per million output tokens through the API. GPT-6.2 Sol retains GPT-6.1 Sol’s prices: $2 per million input tokens, $0.10 per million cached input tokens and $10 per million output tokens.
Astra for professional work
OpenAI trained Astra to handle professional requirements more reliably in law, finance and accounting. The company also says the model produces better presentations: it uses the template’s layouts, colors and fonts, follows font sizes precisely, writes slide titles that reflect each slide’s main point, and uses the body text for key details.
On Agents’ Last Exam, a benchmark for multistep workflows, Astra scored 5.2 points higher than GPT-6 Astra while costing less than a third as much. OpenAI says Astra also scored 5.5 points higher than Claude Fable 5.2 at 5% of that model’s cost. Only Google’s Gemini 4 Carbon competes with Astra in this test.
The legal benchmark Harvey LAB-AA tests tasks such as analyzing contract clauses. OpenAI says Astra more than doubled Claude Fable 5.2’s share of successful answers while costing about six times less. On the company’s internal GDPval-v2 benchmark, which includes consulting, finance and design tasks, Astra gained 6.2 percentage points over its predecessor while using 22% fewer output tokens.
OpenAI says Astra has also improved at computer use, already a strength of the previous model. In tests, Astra created a 3D car model, wrote a physics simulator in Python and animated the result in Blender. In another demo, the model assembled a remote-controlled car from individual parts and produced an animated assembly guide.
On the AA-3D benchmark, judges compare two interactive 3D works without knowing which models created them. Astra ranked first with an Elo rating of 1318. Claude Fable 5.2 scored 1271, and GPT-6.2 Sol scored 1259.
On Terminal-Bench-Science, which tests scientific workflows in the command line, Astra outscored GPT-6 Astra by 9 percentage points while costing less than a third as much. OpenAI also says the model set a new record on the Vals Science Index, which evaluates biological data interpretation and experimental work.
Sol for everyday work
GPT-6.2 Sol is designed for fast, varied everyday tasks. On FrontierCode 2.0, which tests whether code changes meet the requirements of real projects, Sol trailed Astra by just 0.5 points while costing five times less. OpenAI says the model also handles tasks outside work well.
The company says both new models are better at cybersecurity: they find and exploit vulnerabilities more effectively, write more secure code and fix bugs. In several tests, the models also used noticeably fewer tokens. At the same time, GPT-6.2 Astra and Sol, like GPT-6 Astra before them, reached the “Critical” level in OpenAI’s preparedness framework.
In response, the company introduced stricter restrictions on potentially dangerous cybersecurity requests. These are intended to make abuse harder, but OpenAI acknowledges that they will also hinder legitimate vulnerability research and security testing.
OpenAI plans to make the new models available through OpenAI Daybreak. The project already gives vetted security researchers access to other models with less restrictive safeguards. The published cybersecurity results come from internal tests in which safeguards and classifiers were disabled. The methodology is described in the accompanying safety report.
The ExploitBench report compares models’ success rates at different output lengths.
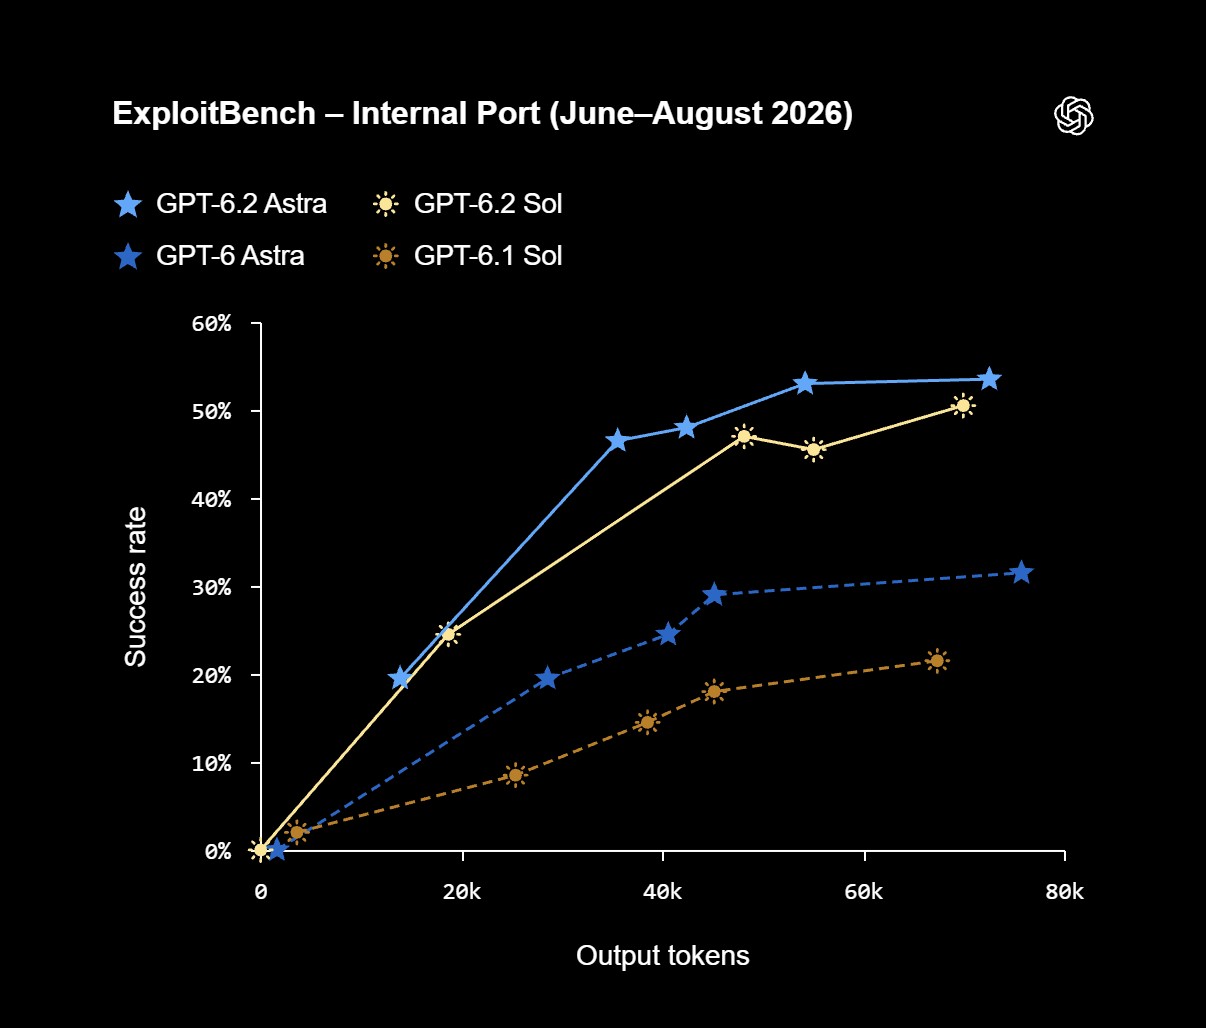
On the internal ExploitBench test, models must turn known browser vulnerabilities into working exploits. GPT-6.2 Astra clears a 50 percent success rate, far outpacing its predecessor GPT-6 Astra. Results come from tests with safeguards turned off. | Image: OpenAI
Source: the-decoder.com
Source: the-decoder.com
Artificial Analysis results
The Artificial Analysis Intelligence Index combines nine evaluations covering professional tasks, coding, science and general knowledge. Astra ranked second, behind only Claude Fable 5.2. According to Artificial Analysis, it gained five points over GPT-6 Astra and outscored Google’s Gemini 4 Carbon, which scored 60, and Anthropic’s Claude Opus 5.5, with 59. Sol gained two points to reach 57, matching GPT-6 Astra, while the cost of a task for Sol is about 15% of what it costs with its predecessor.
On the price-performance frontier, OpenAI models occupy the top positions—the point beyond which no model is both cheaper and more capable. Anthropic and Meta models are also represented in this range. OpenAI also holds most of the top spots in the efficiency ranking, which measures output tokens per task. Claude Fable 5.2 is the only model from another company to appear there.
Independent evaluations broadly support OpenAI’s claims on scientific and factual tasks. Astra leads on Terminal-Bench-Science 0.1 and, in the physical reasoning test CritPt v2, the factual knowledge benchmark AA-Omniscience and the HLE-Diamond knowledge test, trails only Claude Fable 5.2. It also ranked first in 3D design on AA-3D and in robotics on AA-Robotics v0.1: Astra scored 79 in robotics, compared with 78 for Sol and 75 for Claude Fable 5.2.
The coding results are weaker. According to Artificial Analysis, neither model improved here: Astra matched GPT-6 Astra on the agentic coding Index, measured with the Codex harness at maximum compute. Sol lost three points compared with GPT-6.1 Sol. The result was affected by a 14-point drop on SWE-Atlas-QnA-AA: Sol omitted important facts in its answers more often than its predecessor.
Artificial Analysis also reports a high hallucination rate at maximum effort: 59% for Astra and 55% for Sol. The AA-Omniscience Hallucination Rate measures how often a model guesses an answer to a factual question instead of admitting it does not know. The test uses unusually difficult questions, so these figures do not reflect the frequency of errors in everyday use.
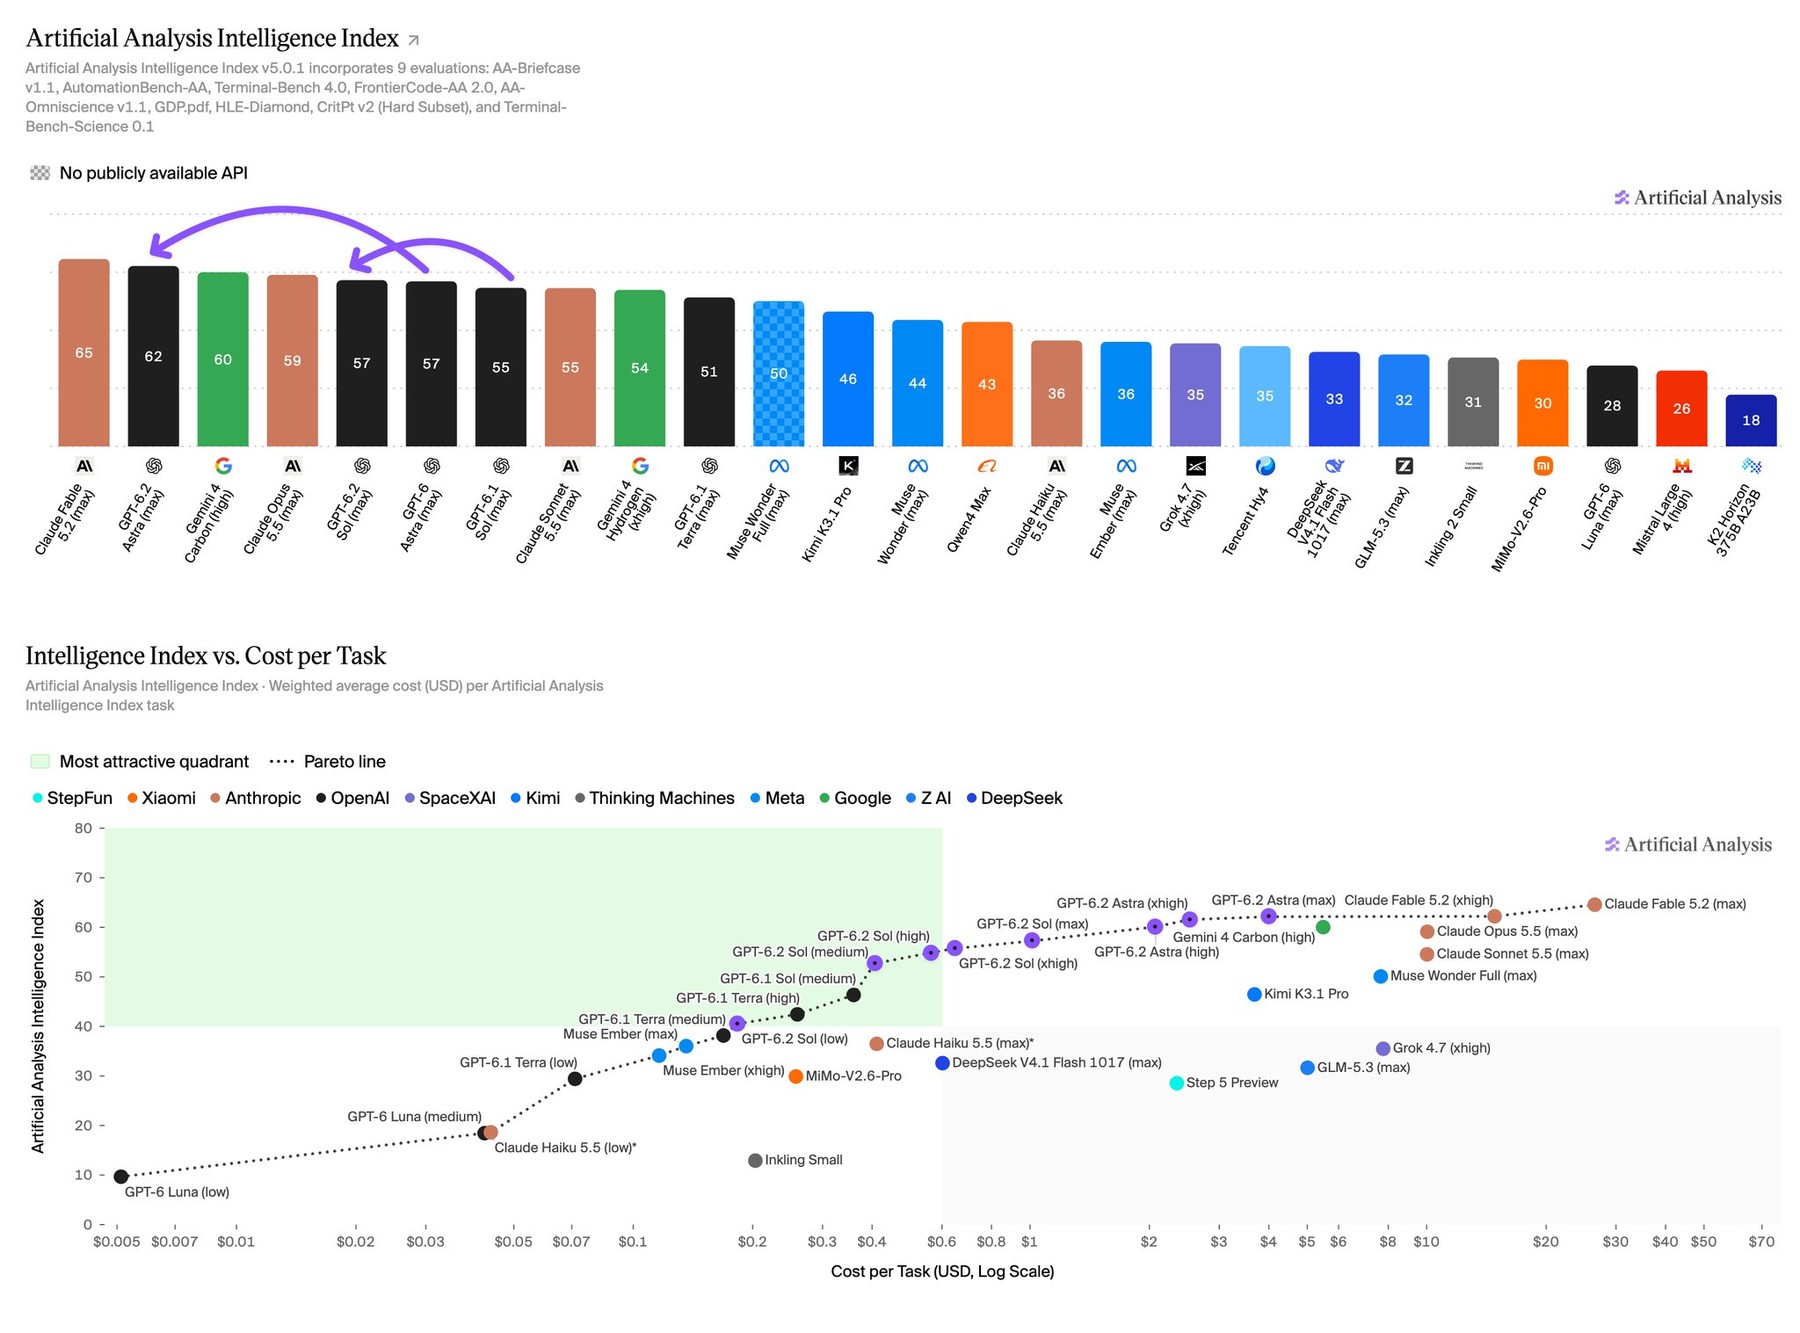
GPT-6.2 Astra reaches 62 points, taking second place in the Intelligence Index just behind Claude Fable 5.2 (65). OpenAI models dominate the Pareto frontier on cost-performance. | Image: Artificial Analysis
Source: the-decoder.com
Epoch AI assessment
Before the model’s release, the research organization Epoch AI tested Astra on its own benchmarks. Astra scored 174 on the Epoch Capabilities Index, matching Anthropic’s Fable 5.2. In Epoch AI’s assessment, both models outperformed the result predicted by the previous trend in the development of reasoning models.
On practical tasks from Epoch AI’s research, Astra trailed Fable 5.2 and only slightly improved on GPT-6 Astra. In simple research projects, it missed the central question and spent time trying to fix problems as they arose. In a task about researching AI data centers, the model was too cautious and left out key estimates—an omission that, Epoch AI said, a contractor could not afford to make. The organization rated Astra’s style as comparatively strong against other models it tested, but still short of its own standards.
Epoch AI separately noted Astra’s ability to carry out complex reasoning within a single output token without showing its chain of thought. The model completed 12.3 consecutive steps, compared with 10.5 for GPT-6 Astra and 4.2 for Claude Fable 5.1, then the strongest model outside OpenAI. Models that reason this way without showing their work are harder to monitor. This safety issue had already arisen with the first Astra model.
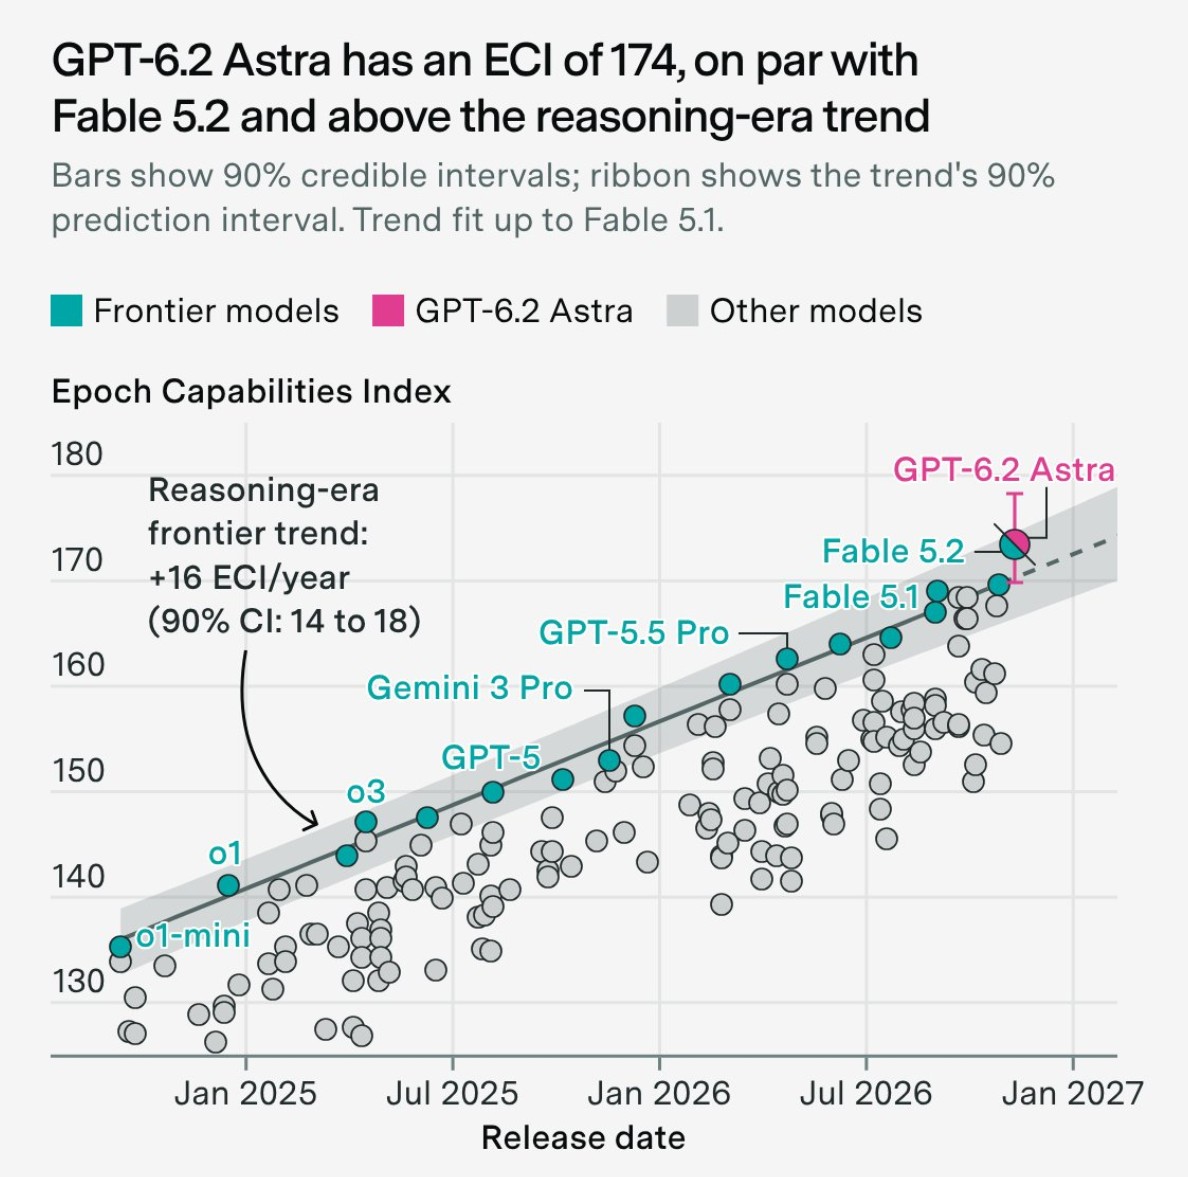
GPT-6.2 Astra scores 174 points in the Epoch Capabilities Index, tying Anthropic's Fable 5.2. Both sit above the previous trend line for reasoning models. Astra is significantly cheaper. | Image: Epoch AI
Source: the-decoder.com
On FrontierMath Erdős, which tests solutions to unsolved mathematical problems, GPT-6.2 Astra solved 7 of 68 tasks. Each solution was formally verified in the Lean proof system. The previous record was 3 of 68, held by GPT-6.1 Sol. One of Astra’s seven solutions was not previously known.
Vals AI rankings
Astra ranked seventh in the Vals Index, and Sol ranked ninth. They are separated by just 1.6 points, but their task costs differ considerably: Vals AI says Sol costs $3.18 per task, less than a third of Astra’s $10.68. It is the cheapest model in the top ten. Astra is also cheaper than its predecessor: it scored 2.6 points higher than GPT-6 Astra and costs about half as much as the predecessor’s $21.28 per task. Among the top ten, Astra uses the fewest output tokens, averaging 91,000 per task.
Vals AI confirms OpenAI’s lead in the science portion of the rankings. Astra ranked first on the Vals Science Index and also led on Terminal-Bench Science and VCB 1–100. Compared with GPT-6 Astra, these tasks took about half as much money and time. Sol ranked third on Terminal-Bench Science while costing about four times less than Astra. In the broader agentic coding test Terminal-Bench 4, Astra ranked fifth and Sol seventh.
The models are less successful on legal tasks. On the HLAB benchmark, Astra and Sol doubled their predecessors’ results but ranked only 11th and 21st. Their results were lower on Legal Research: Astra ranked 30th and Sol 52nd. Vals AI says the models use tools almost twice as often as their predecessors but produce shorter answers.
In September, OpenAI announced a specialized product, Astra for Law. On Legal Research Bench, it significantly outperforms the base model and ranks sixth. Vals AI tested both models with a one-million-token context window, a limit of 128,000 output tokens and maximum reasoning effort.
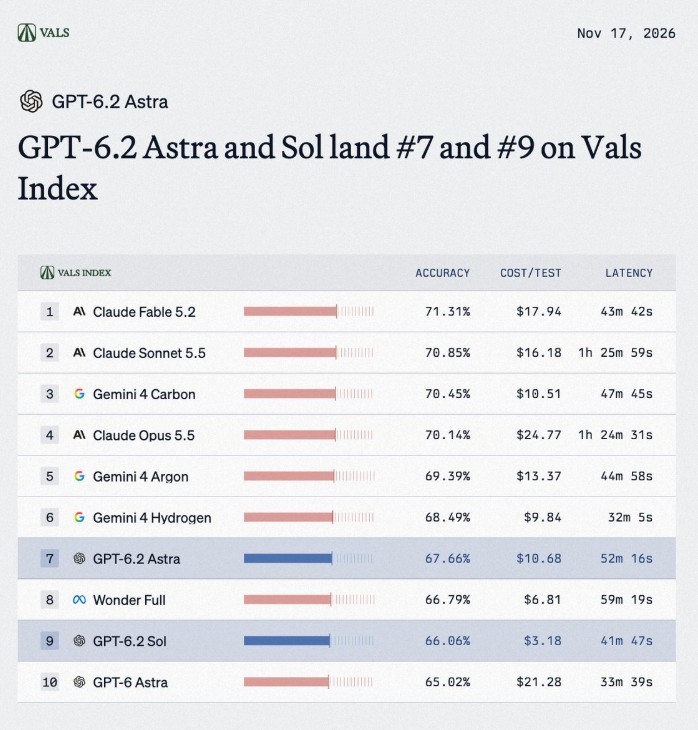
GPT-6.2 Astra and Sol rank 7th and 9th in the Vals Index. Sol runs $3.18 per task, less than a third of Astra's $10.68, and is the cheapest model in the top 10. Claude Fable 5.2 tops the ranking. | Image: Vals AI
Source: the-decoder.com
Source: the-decoder.com
Self-improvement and following instructions
OpenAI says GPT-6.2 Astra is the first model released outside the company to reach the “High” level for its ability to help improve AI systems. The company estimates that Astra could significantly speed up AI research, as if every OpenAI researcher had an additional highly skilled research engineer working with them.
OpenAI considers this capability a risk: models that help create the next generation of AI systems could accelerate the field so much that safety measures and human oversight cannot keep pace. The industry is currently discussing this problem under the name RSI.
OpenAI points to stricter restrictions in research environments and its Control Room monitoring system as safeguards. Control Room tracks research tasks and can stop them when necessary. The company has also expanded its monitoring of how models reason and act, and added automatic alerts for unauthorized behavior.
In tests of how well the models follow user intent and communicate openly, the new models matched their predecessors. However, in two tests, they were more likely not to report obstacles to completing a task, such as a missing file or an unavailable search tool.
Dataist’s take: The new models have made notable gains in scientific and some professional tasks, but their results in coding and legal evaluations are mixed. Price comparisons also depend on the use case: Sol costs less, while Astra’s results vary by type of work. Astra’s ability to speed up AI research comes with a risk that OpenAI intends to contain through monitoring and restrictions.
Daily AI news
Every day we pick what actually matters in AI and explain it plainly — no hype, no filler. Subscribe if you want to follow where the industry is going.
Only what matters — every day
Follow on X