
Why failure logs reach a limit
Many agent optimizers learn from execution traces. Some, including WikiSkill from Google, SkillOpt from Microsoft, and Memento-Skills, improve a single component such as a skill library or memory store. Others, including Salesforce’s DarwinX, Xiaomi’s HarnessX, Self-Harness, and Stanford’s Meta-Harness, use a meta-agent to rewrite code or operating rules after examining failed runs.
The researchers argue that trace-driven systems are limited by what their base model already knows. A failure may reveal that an agent cannot handle a particular problem, but not how to fix that weakness. In one example, repeated search and Python-tool errors prompted a system to add a checker for every action. It caught invalid calls, but became so cautious that it blocked valid API requests.
There is a timing problem, too: an optimizer needs failures to accumulate before it can learn from them. In a live system, users may encounter a weakness before the agent has collected enough evidence to improve.
Turning papers into modules
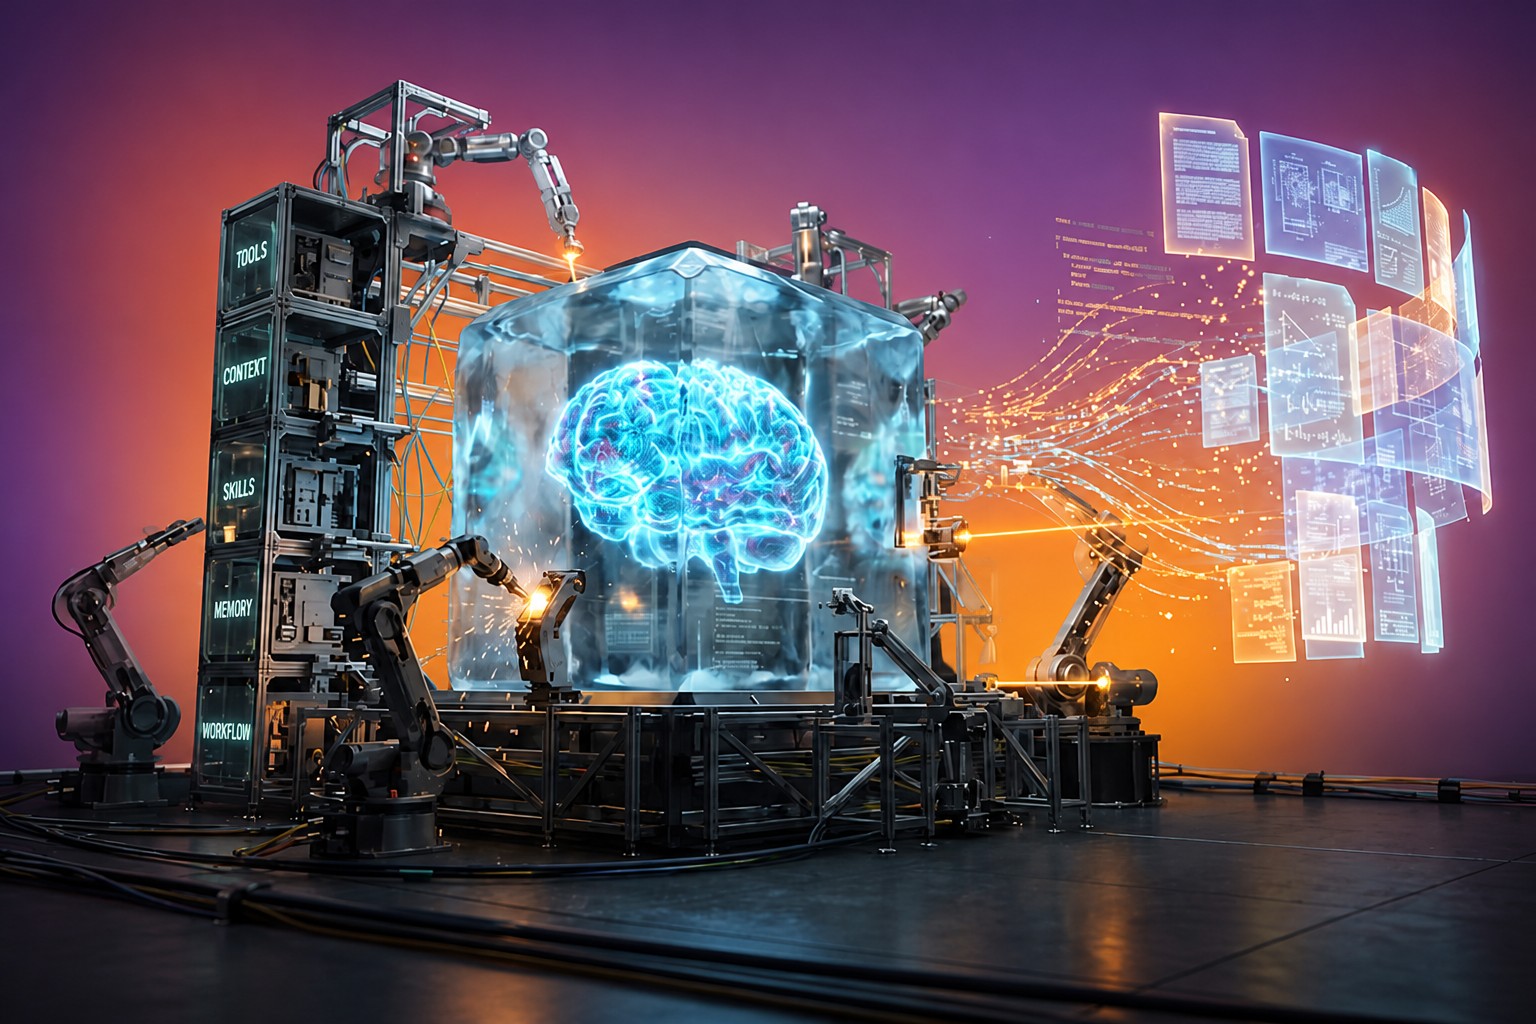
ScholarEvolve separates an agent’s harness into five modules: tool interfaces, context management, skills, memory, and workflows. It then searches for research relevant to weaknesses found in training tasks, implements candidate changes in one module at a time, and tests the resulting combinations.
The process has four stages:
On Qwen3.5-27B in AppWorld, the researchers report three kinds of changes: an abstract syntax tree check for Python calls and an API-documentation macro based on ToolACE-R; a query-aware context budget that scores conversation history by relevance and recency; and typed pseudocode templates that reuse successful API sequences, drawing on Skill-as-Pseudocode.
What the scores show
ScholarEvolve improved both base models across all reported measures. In AppWorld, Qwen3.5-27B’s task goal completion (TGC) rose by 12.4 percentage points, and scenario goal completion (SGC) rose by 20.2 points. SGC requires an agent to complete three variants of the same scenario. In Telecom, GPT-5.4-mini improved from 72.7% to 81.9%.
The results also suggest that a harness can change how much of a model’s capability shows up in practice:
I think the module-combination result is the most useful finding for teams considering this approach. A component that looks weaker on its own can produce the stronger system once paired with other changes. That makes isolated module scores a poor guide to what should ship.
The missing security gate
The paper’s automated checks cover whether code imports, fits the interfaces, creates artifacts, and produces valid actions. They do not describe checks for malicious dependencies, unsafe execution, or prompt-injection vulnerabilities in papers and third-party code. The authors point to a GitHub repository, but it was empty at publication; the paper’s appendices include code excerpts for five selected modules.
My guess is that this is the harder engineering problem than finding promising papers. A team could direct the framework to a curated internal repository or put a security review gate between generated code and deployment. Either way, the reported results do not establish that ScholarEvolve can safely update a production agent without human review.
The researchers ran three successive literature-based update rounds on AppWorld Normal without changing Qwen’s weights or the task data already collected. Performance improved after each round, but the experiments did not test continuous adaptation in production. The framework may help teams prepare for failures before users encounter them; whether that advantage survives a security review and real deployment remains unproven.
Daily AI news
Every day we pick what actually matters in AI and explain it plainly — no hype, no filler. Subscribe if you want to follow where the industry is going.
Only what matters — every day
Follow on X