i
DATAIST
Back to feed

Multimodality

Text, sound, image and video in a single model.

2 articles

Self-written explanations are what let models read dark humor in memes

Not all jokes work the same way. Clean humor runs on wordplay and harmless incongruity; dark humor runs on painful subjects, cultural references and fine contrasts between the image and the caption. In memes this is especially visible: the picture says one thing, the text says another, and the meaning appears where they meet. Until recently there was no good multimodal dataset for dark humor…
DeepSeek's V4.1-Flash targets the memory bill, not the leaderboard

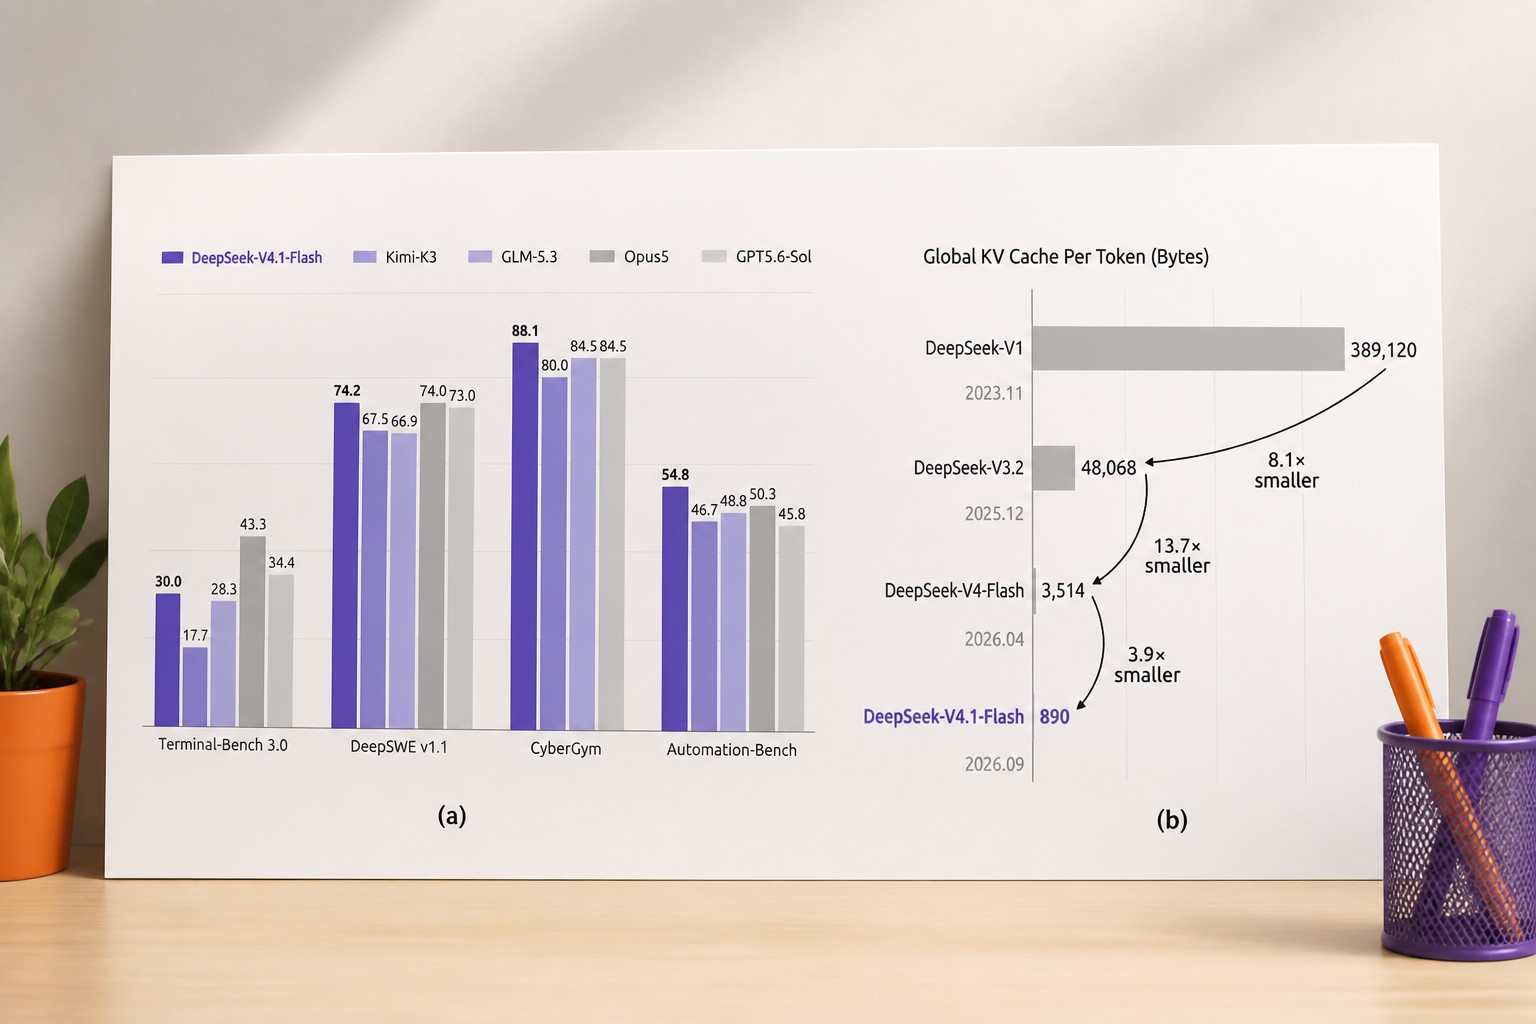
DeepSeek has released V4.1-Flash, a multimodal model whose pitch is a memory bill rather than a benchmark. The KV cache — the buffer that holds already-processed context so the model does not recompute it at every step — now occupies roughly a quarter of the fast GPU memory that DeepSeek-V4-Flash needed, and the portion permanently offloaded to SSD or host memory falls to about an eighth. The…